
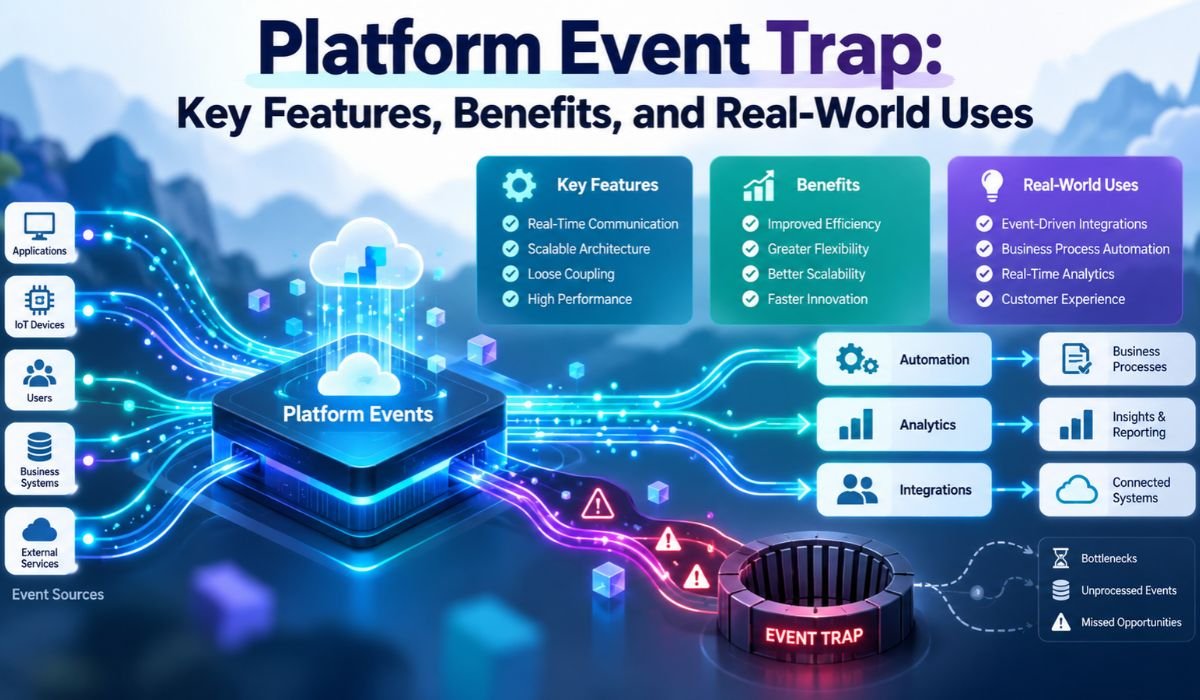
Modern software development runs on automation. A developer makes a change, the pipeline starts, tests run, an artifact is created, approvals are checked, and the software may eventually reach production. Much of this can happen with very little human involvement. That speed is one of the biggest strengths of modern development, but it also creates a challenge: security problems can move through the same automated path just as quickly.
This is where the idea of a Platform Event Trap becomes useful. In the CI/CD security context covered here, the term describes an event-driven security pattern that reacts when a specific activity breaks a defined policy. Rather than simply generating an alert and waiting for someone to investigate, the control can intervene while the risky action is still taking place. Depending on how the system is configured, it might block a merge, fail a build, pause a deployment, request another approval, or start a security response.
The goal isn’t to stop every unusual event. Instead, a well-designed Platform Event Trap places reliable security controls at points where a dangerous action can still be prevented or contained. Used thoughtfully, this approach can strengthen CI/CD Security, DevSecOps, cloud governance, secrets protection, and automated policy enforcement without making everyday development unnecessarily difficult.
Quick Bio Information
| Information | Details |
|---|---|
| Primary Term | Platform Event Trap |
| Article Context | CI/CD And Event-Driven Security |
| Core Purpose | Respond To Defined Policy Violations |
| Main Approach | Event-Driven Enforcement |
| Common Environment | Software Delivery And Cloud Automation |
| Typical Event Source | Repository, Pipeline, Cloud, Or Identity System |
| Policy Function | Determine Whether Activity Meets Requirements |
| Possible Response | Block, Pause, Escalate, Or Remediate |
| CI/CD Role | Enforce Security During Software Delivery |
| Secret Security | Can React To Confirmed Credential Exposure |
| Identity Relevance | Human And Non-Human Access |
| DevSecOps Role | Integrate Security Into Delivery Workflows |
| Audit Value | Record Policy Decisions And Responses |
| Major Operational Risk | False Positives |
| Automation Risk | Incorrect Or Excessive Remediation |
| Security Principle | Least Privilege And Controlled Enforcement |
| Reliability Requirement | Trusted Events And Observable Responses |
| Recommended Starting Point | High-Risk, High-Confidence Events |
What Is A Platform Event Trap?
In software delivery security, a Platform Event Trap can be described as a control pattern that connects an important platform event with a security decision and, when necessary, an immediate response.
The event could be a pull request, pipeline configuration change, secret-scanning result, deployment request, identity event, or cloud infrastructure change. Once that event occurs, the system examines the available context and compares it with predefined security requirements. If everything is acceptable, the workflow continues. If the activity violates policy, the system can block it, pause it, escalate it for review, or initiate an approved remediation process.
There is an important terminology issue to understand. Platform Event Trap isn’t a universally standardized name for this type of CI/CD security control. The abbreviation PET also has a long-established meaning in IPMI hardware management, where a Platform Event Trap is used to report hardware platform events. The same phrase can therefore describe different concepts depending on where it appears.
For this article, Platform Event Trap specifically refers to event-driven security enforcement within software delivery, cloud automation, and related workflows.
How A Platform Event Trap Works
At its simplest, the process involves three things: an event happens, a policy evaluates it, and the system decides how to respond.
Suppose a developer accidentally includes an API credential in a proposed code change. A secret-scanning system detects the credential and generates a finding. The organization’s security policy states that confirmed secrets aren’t allowed in protected branches, so the workflow prevents the change from being merged.
What happens next depends on the organization’s security setup. The development or security team may investigate the finding. If the credential is genuine and has been exposed, an integrated secrets-management or identity system may be able to rotate or revoke it.
That distinction matters. Detecting an exposed secret doesn’t automatically mean the credential has been disabled. Successful containment depends on the integrations, permissions, policies, and identity systems surrounding the workflow.
A mature system also records what happened. Useful audit information should explain which event occurred, which policy was evaluated, why the action was blocked or allowed, what automated response followed, and whether human intervention was necessary.
Key Features Of Platform Event Trap Security
One of the defining characteristics of Platform Event Trap Security is its ability to move security decisions closer to the event itself. Real-time or near-real-time detection gives organizations an opportunity to react before a risky change travels further through the software delivery process.
Policy evaluation provides the decision-making layer. Rather than assuming every unusual event is dangerous, the system evaluates whether an activity meets the organization’s defined requirements. A legitimate production deployment with the right approvals may proceed normally, while another deployment that lacks required authorization can be stopped.
The response doesn’t always have to be severe. A high-confidence secret exposure might justify immediately blocking a merge. A lower-confidence finding may be better handled by requesting additional review. This ability to match the response to the level of risk is essential for maintaining both security and productivity.
Good controls also communicate clearly. Developers shouldn’t have to guess why a build or deployment was rejected. An effective system explains what failed, which requirement was involved, and what action can resolve the problem.
Core Components Behind Event-Driven Enforcement
A dependable Platform Event Trap begins with a trustworthy source of events. Depending on the environment, that source might be a code repository, CI/CD platform, cloud service, identity provider, secrets manager, artifact repository, or container orchestration platform.
Once an event is generated, it needs to reach a decision layer. A policy engine or similar mechanism examines the event and its context to determine whether the requested activity complies with security requirements. If enforcement is necessary, another component carries out the approved response. Logging and observability systems then record the decision and its outcome.
The connections between these components are easy to overlook, but they’re critical. Event sources should be authenticated where possible so an attacker can’t simply submit fake security events. Automated services should also operate with the minimum permissions required for their job.
Reliability matters just as much. Events can arrive late or more than once. APIs can fail. Policy services can become unavailable. A strong design anticipates these conditions instead of assuming every component will always behave perfectly.
Security Events Worth Monitoring
A common mistake in security automation is trying to enforce a rule around every possible event. More controls don’t automatically create better security. In fact, excessive blocking can produce noise, frustrate developers, and encourage people to find ways around the system.
A better approach is to concentrate on events tied to meaningful risk.
A pull request, for example, can trigger security checks before changes enter a protected branch. Dependency changes can initiate vulnerability or software composition analysis. A confirmed secret-scanning finding can prevent sensitive credentials from moving further through a repository workflow.
CI/CD configuration changes deserve particular attention because pipeline configuration can influence trusted automation and determine which credentials or environments a workflow can access.
Deployment events offer another valuable enforcement point. Before a release proceeds, the system can check required approvals, artifact integrity, environment restrictions, and authorization. Infrastructure automation can apply similar controls to cloud configuration changes before those changes are deployed.
The strongest strategy is selective: focus enforcement where an incorrect decision could create serious consequences.
Benefits Of Platform Event Traps
Speed is one of the clearest advantages. When detection and enforcement are connected, organizations can reduce the time between recognizing a known policy violation and containing it. Instead of discovering a problem after deployment, teams may be able to stop it while the change is still moving through the pipeline.
Consistency is equally valuable. Manual reviews can vary depending on workload, experience, and available context. A well-tested automated policy applies the same requirement each time it encounters the same conditions.
There’s also an important audit benefit. Properly configured controls can preserve evidence showing when a policy was evaluated, why an action was rejected, what automated response occurred, whether an exception was granted, and how the issue was eventually resolved.
Automation becomes particularly useful as engineering organizations grow. Security teams can’t manually inspect every repository action or pipeline event. Automated enforcement can handle predictable decisions, leaving specialists more time for incidents that genuinely require judgment.
Still, automation is only as reliable as the rules behind it. A poorly designed policy doesn’t become a good policy simply because a computer enforces it faster.
Real-World Platform Event Trap Uses
Secret exposure provides an easy example of how event-driven enforcement can work in practice. Imagine that a developer submits a pull request containing what appears to be a live credential. A secret scanner identifies it before the code is merged. If the finding meets the organization’s blocking criteria, the merge can be stopped while the credential is investigated.
If exposure is confirmed, the organization may also need to rotate or revoke the credential. That response depends on whether the relevant identity or secrets-management systems are connected to the workflow and authorized to perform the action.
Software releases offer another practical example. An organization may require release artifacts to meet specific approval, integrity, provenance, or signing requirements. If an artifact doesn’t meet those conditions, promotion can remain blocked until the issue is corrected.
Cloud infrastructure provides similar opportunities. A proposed configuration that violates an approved policy can be rejected before it changes the live environment. Meanwhile, unusual activity involving a privileged workload identity could trigger additional authorization rather than an immediate destructive response.
The common theme is timing. Security decisions happen close to the activity creating the risk instead of only after that activity has already affected production.
Platform Event Trap Vs Traditional Monitoring
Traditional security monitoring and Platform Event Trap Security share some of the same foundations, but their emphasis is different.
Monitoring is primarily about visibility. It collects information, detects unusual behavior, generates findings, and helps security teams understand what is happening across an environment. Event-driven enforcement takes selected events a step further by connecting them to an immediate policy decision.
Imagine a deployment that doesn’t satisfy a required security check. A monitoring system might identify the problem and alert the security team. An enforcement control can prevent the deployment from continuing until the requirement has been satisfied.
That doesn’t mean monitoring systems are incapable of automation. Many modern security platforms can initiate responses of their own. The difference is therefore more about architecture and intent than about a strict division between technologies.
In practice, organizations need both. Monitoring provides broad visibility and investigative context, while carefully targeted enforcement creates stronger guardrails around sensitive actions.
Platform Event Traps In DevOps And DevSecOps
DevOps is built around making software delivery faster, more repeatable, and more reliable. DevSecOps carries security into that same workflow instead of treating it as a separate review at the end of development.
A Platform Event Trap fits naturally into this model because security requirements can be evaluated while software is being built, reviewed, and deployed.
The challenge is finding the right balance. Security teams may understandably want to block anything that looks suspicious, but aggressive enforcement can become counterproductive. When developers repeatedly encounter false positives or unexplained pipeline failures, trust in the security process begins to decline.
That is why the best policies tend to match the response to the confidence and impact of the finding. A high-confidence credential leak involving a sensitive environment may justify immediate blocking. A less certain signal could generate a warning or request human review instead.
Successful DevSecOps depends on collaboration. Security, development, and platform teams should understand why controls exist, how exceptions work, and what developers need to do when something is blocked.
Platform Event Trap And Non-Human Identities
Modern software environments depend heavily on Non-Human Identities. These include service accounts, application identities, workload identities, API keys, certificates, and automation tokens.
Such identities often have significant access. A deployment service may be able to modify production infrastructure. A CI/CD runner may have access to repositories or artifact stores. An application credential may provide access to sensitive data or cloud services.
This makes identity context particularly useful for event-driven security.
A control might react when a credential is exposed in source code, when an automation identity unexpectedly requests additional privileges, or when a workload attempts an operation outside its normal environment.
However, event-driven enforcement shouldn’t become a substitute for sound identity management. Short-lived credentials, least-privilege permissions, secure secret storage, controlled rotation, and clear ownership remain fundamental safeguards. Platform Event Traps work best as another layer around those practices.
Technologies That Support Platform Event Traps
Organizations don’t need a product specifically named Platform Event Trap to implement the concept. The pattern can be built from capabilities already available across source-control systems, CI/CD platforms, policy engines, cloud services, secrets managers, identity systems, and container environments.
Repository and pipeline platforms can produce events and enforce required checks before sensitive actions continue. Policy-as-code technology can evaluate security requirements in a consistent and repeatable way. Secrets-management platforms can support credential lifecycle operations when an exposed secret requires action.
Container environments can apply admission policies before workloads are allowed to run. Cloud event systems can connect infrastructure changes with security automation.
The product label is less important than the architecture. A useful implementation needs a trustworthy event, sufficient context, a clear policy, an authorized enforcement mechanism, and an observable result.
If one of those elements is missing, the control may provide less protection than teams assume.
How To Implement A Platform Event Trap
The safest starting point is usually a small collection of high-risk, well-understood events. Trying to automate every security decision at once creates complexity and makes troubleshooting difficult.
For each selected event, teams should determine what actually counts as a violation. They should also define the evidence required to make that decision, the response that should follow, the team responsible for the policy, and the process for approving legitimate exceptions.
Testing should cover normal activity as carefully as malicious or non-compliant behavior. A control that correctly blocks a simulated attack but repeatedly stops legitimate developers isn’t ready for broad deployment.
Failure testing is just as important. What happens when the same event arrives twice? What if the policy engine is temporarily unavailable? What happens if an API times out after beginning remediation? Could a credential be revoked while the application depending on it remains active?
Teams also need to make a deliberate fail-open or fail-closed decision. For a sensitive production deployment, failure to validate security policy may justify stopping the release. A low-risk development workflow may need a different approach. The right choice depends on the potential impact of allowing the activity versus the operational cost of blocking it.
Risks, Limitations, And Common Mistakes
Security automation can fail in both directions. Rules that are too weak may allow genuine threats through, while rules that are too strict can interrupt legitimate engineering work.
False positives are especially damaging over time. When developers regularly see harmless activity blocked, they may begin to treat security warnings as background noise. In the worst case, teams may seek ways to bypass the controls altogether.
Automated remediation introduces another risk. A service capable of revoking credentials, changing permissions, or modifying infrastructure has significant authority. If that service is compromised or incorrectly configured, the security mechanism itself can become a source of disruption.
Event reliability must also be considered. Messages can be delayed, duplicated, or lost depending on the architecture. Downstream services can fail, and remediation may only partially complete.
For these reasons, teams shouldn’t equate “event received” with “risk resolved.” Good implementations monitor the enforcement mechanism itself, maintain detailed audit trails, provide recovery procedures, control exceptions, and escalate ambiguous situations to people who can make informed decisions.
Standards, Governance, And Trust
The principles behind event-driven enforcement fit comfortably within established cybersecurity practices, even though major frameworks don’t define a universal CI/CD security control specifically called Platform Event Trap.
The NIST Cybersecurity Framework addresses the broader activities organizations use to understand, manage, detect, respond to, and recover from cybersecurity risk. Secure software development guidance likewise encourages organizations to integrate security practices throughout software development rather than leaving security until the final release stage.
Zero Trust principles reinforce another relevant idea: access shouldn’t remain trusted simply because an identity or system was trusted previously. Authorization, context, and least-privilege access continue to matter as systems and conditions change.
Non-Human Identity security guidance also draws attention to risks involving leaked secrets, excessive privileges, identity lifecycle weaknesses, and insecure automated environments.
These frameworks and security practices support the broader reasoning behind event-driven enforcement. They shouldn’t, however, be presented as formally defining or universally requiring something called a Platform Event Trap.
Measuring Whether The Control Actually Works
The number of blocked events is a poor measure of security on its own. A control that blocks hundreds of harmless actions may look busy while providing little real protection.
Instead, teams should examine whether genuine policy violations are identified accurately and contained quickly. They should monitor false positives, successful and failed enforcement actions, exception requests, and the operational impact of security checks.
Developer experience is another useful signal. When a workflow is blocked, can the developer understand what happened? Is the reason clear? Can the issue be corrected without unnecessary escalation? Security controls become far more sustainable when they help people resolve problems rather than simply telling them that something failed.
Policies also need regular review. Applications change. Pipelines evolve. New services and identities appear. Threats shift. A rule that made sense when it was created may become outdated as the environment changes.
Effective measurement therefore combines security outcomes with reliability and usability. The objective isn’t maximum blocking. It’s accurate, dependable intervention where intervention genuinely reduces risk.
Final Thoughts
A Platform Event Trap is best understood here as an event-driven security pattern, not as a single product or an officially standardized CI/CD control. Its value comes from connecting meaningful platform events with clear security policies while there is still time to prevent or contain risky activity.
Done well, this approach can strengthen software pipelines, cloud environments, secrets management, and Non-Human Identity security. It can also reduce the gap between recognizing a problem and taking useful action.
The strongest implementations aren’t necessarily the ones that block the most activity. They’re the ones that identify important risks accurately, respond proportionately, explain their decisions, operate with limited privileges, and remain dependable when other systems fail.
That distinction becomes increasingly important as software delivery grows more automated. Machines are making and executing more workflow decisions, often using powerful credentials and trusted access. Security controls need to operate at comparable speed, but speed alone isn’t enough.
A good Platform Event Trap combines automation with judgment. It places guardrails where they matter, keeps humans involved when context is uncertain, and gives engineering teams a safer way to move quickly.
FAQs About Platform Event Trap
What Is A Platform Event Trap?
In the CI/CD security context discussed in this article, a Platform Event Trap is an event-driven enforcement pattern. It identifies selected workflow events, evaluates them against security requirements, and initiates an appropriate response when a policy violation is detected. Depending on the situation, that response might involve blocking, pausing, escalating, or starting a remediation process.
Is Platform Event Trap An Official Cybersecurity Standard?
No. Platform Event Trap isn’t a universally standardized name for a CI/CD cybersecurity control. The term PET also has an established meaning in IPMI hardware management, where it relates to reporting hardware platform events. Context is therefore important whenever the phrase appears.
Is A Platform Event Trap The Same As A Webhook?
No. A webhook is generally a mechanism for informing another system that an event has occurred. In the security context used here, a Platform Event Trap describes a broader process. The event must be received, evaluated against policy, connected to a decision, and followed by an appropriate response. A webhook could be one component of that architecture.
Can Platform Event Traps Prevent Cyberattacks?
They can prevent or contain certain types of risky activity, but no Platform Event Trap can guarantee protection against every attack. Effectiveness depends on the quality of the policies, the events being monitored, integration reliability, identity security, permissions, and the organization’s wider defensive controls.
Can Platform Event Traps Protect API Keys And Secrets?
They can help. When connected to reliable secret-scanning and credential-management systems, an event-driven control can stop a merge or deployment after a confirmed secret exposure. It may also initiate investigation or credential rotation. Actual revocation depends on the identity or secrets-management integrations available and the permissions granted to them.
Are Platform Event Traps Useful For DevSecOps?
Yes. The concept fits naturally with DevSecOps because it brings security decisions directly into development and deployment workflows. Instead of waiting until the end of software delivery, teams can evaluate selected security requirements while code and infrastructure changes are still moving through the pipeline.
Can Platform Event Traps Slow Down CI/CD?
They can if they’re poorly designed. Too many synchronous checks, slow policy services, or frequent false positives can delay builds and deployments. Teams can reduce that impact by concentrating on meaningful risks, optimizing policy evaluation, and reserving automatic blocking for situations where the security benefit justifies the interruption.
What Makes A Platform Event Trap Trustworthy?
Trustworthy implementations depend on authenticated event sources, accurate policies, least-privilege permissions, reliable event delivery, detailed audit records, controlled exceptions, safe failure behavior, clear ownership, and regular testing. Teams should also monitor the enforcement system itself. A security control that fails silently can create a dangerous sense of protection without actually providing it.
Learn more and explore exciting content on: What Is a Content Roadmap and Why Does Your Strategy Need One?
[…] Learn more and explore exciting content on: Platform Event Trap: Key Features, Benefits, and Real-World Uses […]